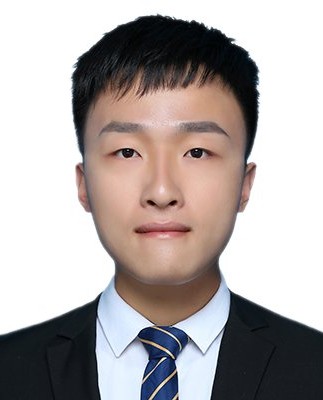
Qinghe Wang | 王清和

alt text 

I am a fourth-year PhD student at the IIAU-Lab in Dalian University of Technology, under the supervision of Prof. Huchuan Lu (IEEE Fellow) and Prof. Xu Jia. I am selected into the China Association for Science and Technology (CAST) Young Talent Support Program - Doctoral Student Initiative. I obtained my Master's degree from Tianjin University supervised by Prof. Pengfei Zhu and Prof. Bing Cao. I obtained my Bachelor's degree from Dalian Maritime University. My research focuses on Video World Models.

[GitHub] [Google Scholar] [X] [E-mail: aitwqh@163.com]

Graduating in 2027, actively seeking 2026 recruitment opportunities. Please feel free to contact me!

News

[2026/9]  Release HappyWorld-Bench.
[2026/6]  Know3D and SMARLI are accepted to ECCV 2026.
[2026/5]  Start a research internship at HappyOyster Team, advised by Wenbo Su.
[2026/4]  VFXMaster and EasyVFX are accepted to SIGGRAPH 2026.
[2026/3]  MultiShotMaster, Group Editing and Video2LoRA are accepted to CVPR 2026.
[2026/1]  Win First Prize (🥇 1st Place) at the AAAI CVM 2026 Main Track.
[2026/1]  Release Controllable Video Generation: A Survey.
[2025/12]  Selected into the CAST Young Talent Support Program - Doctoral Student Initiative.
[2025/12]  Release SemanticGen.
[2025/11]  Release RelightMaster.
[2025/4]  CineMaster is accepted to SIGGRAPH 2025.
[2025/3]  CharacterFactory is accepted to TIP 2025, and StableIdentity is accepted to TMM 2025.
[2024/8]  MoBox is accepted to TCSVT 2024.
[2024/7]  MoTrans and Inverted Interaction are accepted to ACMMM 2024.
[2024/7]  Start a research internship at Kling Team, advised by Xiaoyu Shi and Xintao Wang.
[2024/4]  Release CharacterFactory with a Gradio Demo.
[2024/1]  Release StableIdentity. LeCun: OMG.

Internships
alt text 

Alibaba
2026.5~Now Research Intern in HappyOyster Team, Alibaba Group (Beijing)  
Advisor: Wenbo Su
Topic: Real-Time Interactive Streaming Video Generation

alt text 

Kuaishou
2024.7~2026.5 Research Intern in Kling Team, Kuaishou Technology (Shenzhen)  
Advisors: Xiaoyu Shi, Xintao Wang
Topic: Video Generation

alt text 

ByteDance
2022.4~2022.12 Research Intern in ByteDance Intelligent Creation Lab (Beijing)  
Advisors: Lijie Liu, Qian He
Topic: Image Generation

Selected Publications

alt text 

[Technique Report]  
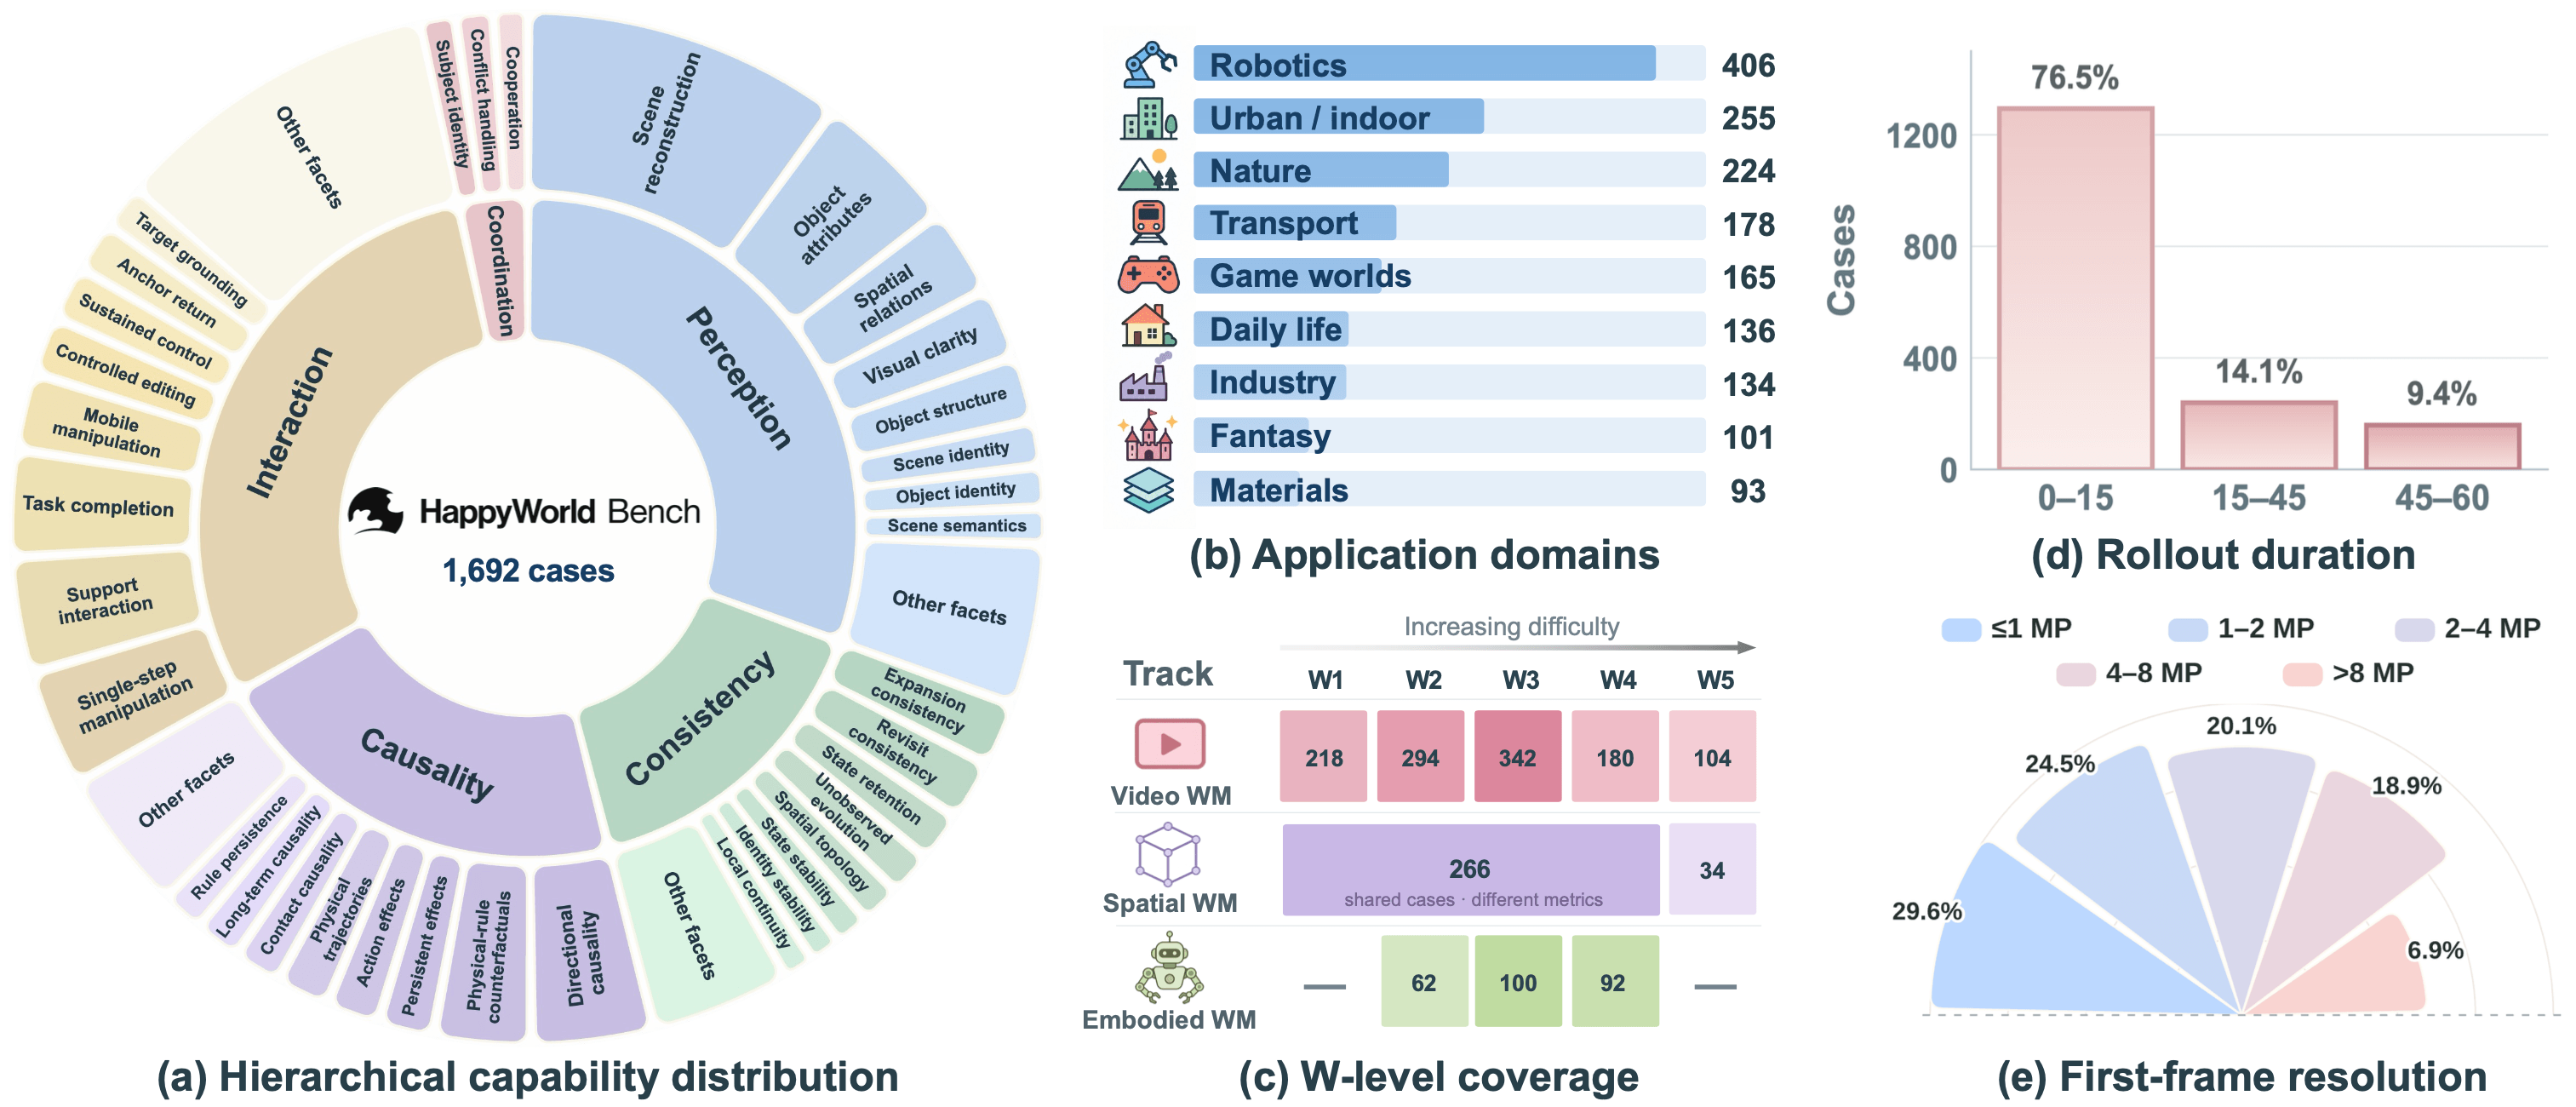
HappyWorld-Bench
Zhiqi Bai, Junai Cai, Yixin Chen, Jingrun Du, Tao Feng, Wei Gong, Siyuan Huang, Xiao Lin, Jiaheng Liu, Jun Luo, Yongzhe Lyu, Liya Ma, Zenan Meng, Lin Qu, Wenbo Su, Jiaming Wang, Qinghe Wang, Shaofei Wang, Yanghai Wang, Zequn Wang, Ziming Wang, Hu Wei, Jiangtao Wu, Ruiqi Wu, Jiaxin Xie, Yuchi Xu, Ze Xu, Chengting Yu, Liangyu Yuan, Gang Zeng, Yawen Zeng, Xingyao Zhang, Zizheng Zhang, Bo Zheng, Jiancheng Zhu, Song-Chun Zhu (Listed in alphabetical order)
[Paper] [Project Page]

Benchmarking the reliability of video, spatial, and embodied world models.

alt text 

[CVPR 2026 CCF A]  
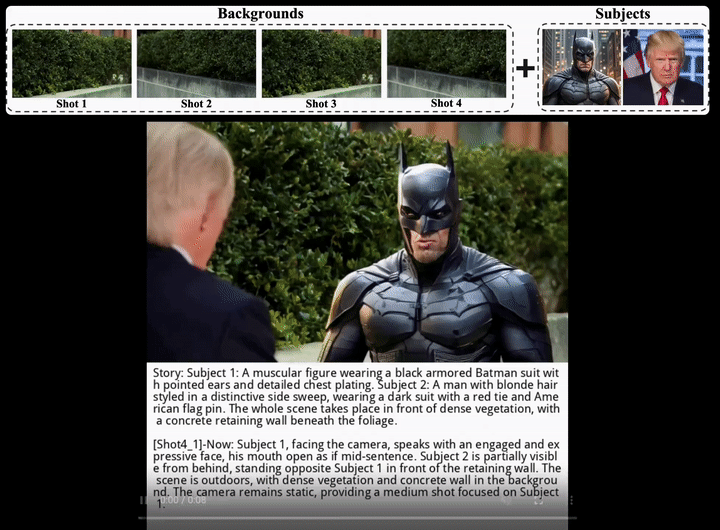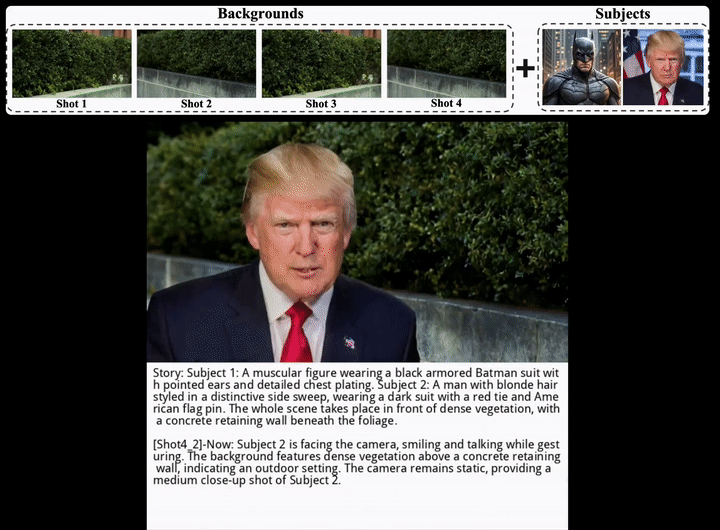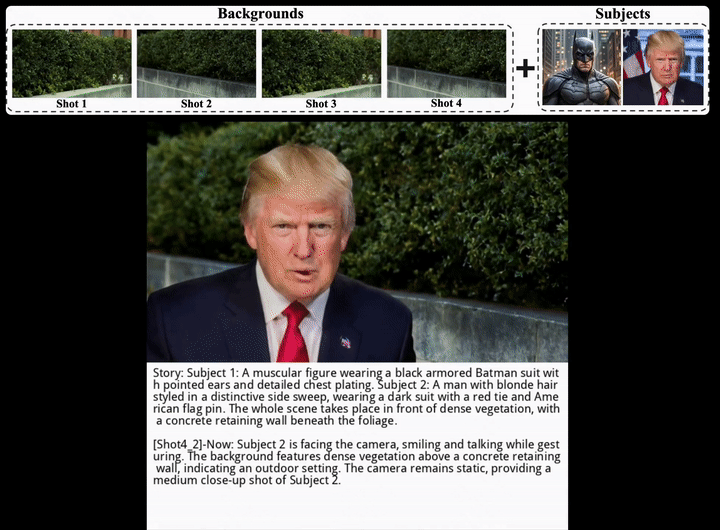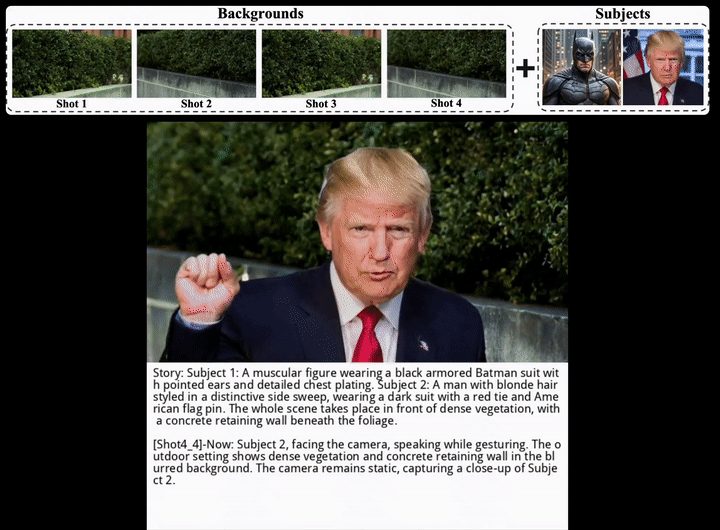
MultiShotMaster: A Controllable Multi-Shot Video Generation Framework
Qinghe Wang, Xiaoyu Shi✉, Baolu Li, Weikang Bian, Quande Liu, Huchuan Lu, Xintao Wang, Pengfei Wan, Kun Gai, Xu Jia✉
[Paper] [Project Page] [Code] [🥇 1st Place at AAAI CVM 2026]

The first controllable multi-shot video generation framework that supports text-driven inter-shot consistency, customized subject with motion control, and background-driven customized scene. Both shot counts and shot durations are variable.

alt text 

[SIGGRAPH 2026 CCF A]  
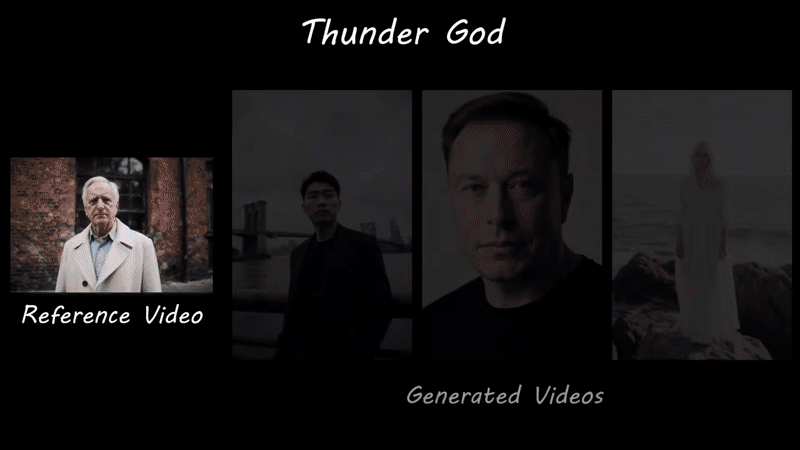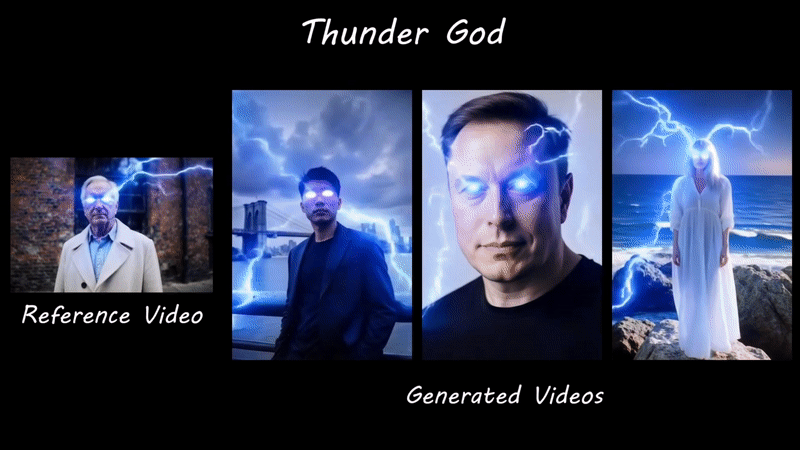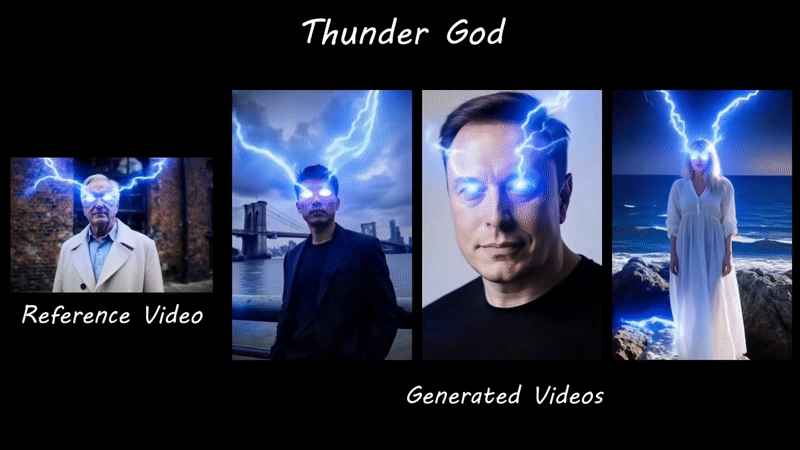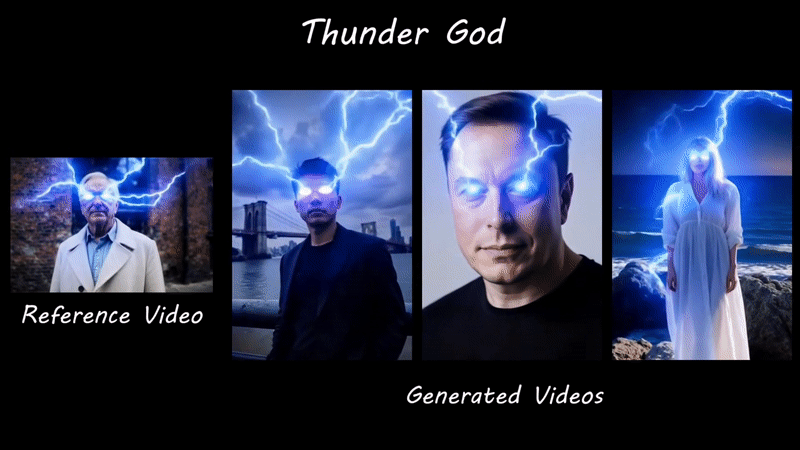
VFXMaster: Unlocking Dynamic Visual Effect Generation via In-Context Learning
Baolu Li*, Yiming Zhang*, Qinghe Wang(co-first, Project Lead), Liqian Ma✉, Xiaoyu Shi, Xintao Wang, Pengfei Wan, Zhenfei Yin, Yunzhi Zhuge, Huchuan Lu, Xu Jia✉
[Paper] [Project Page] [Code]

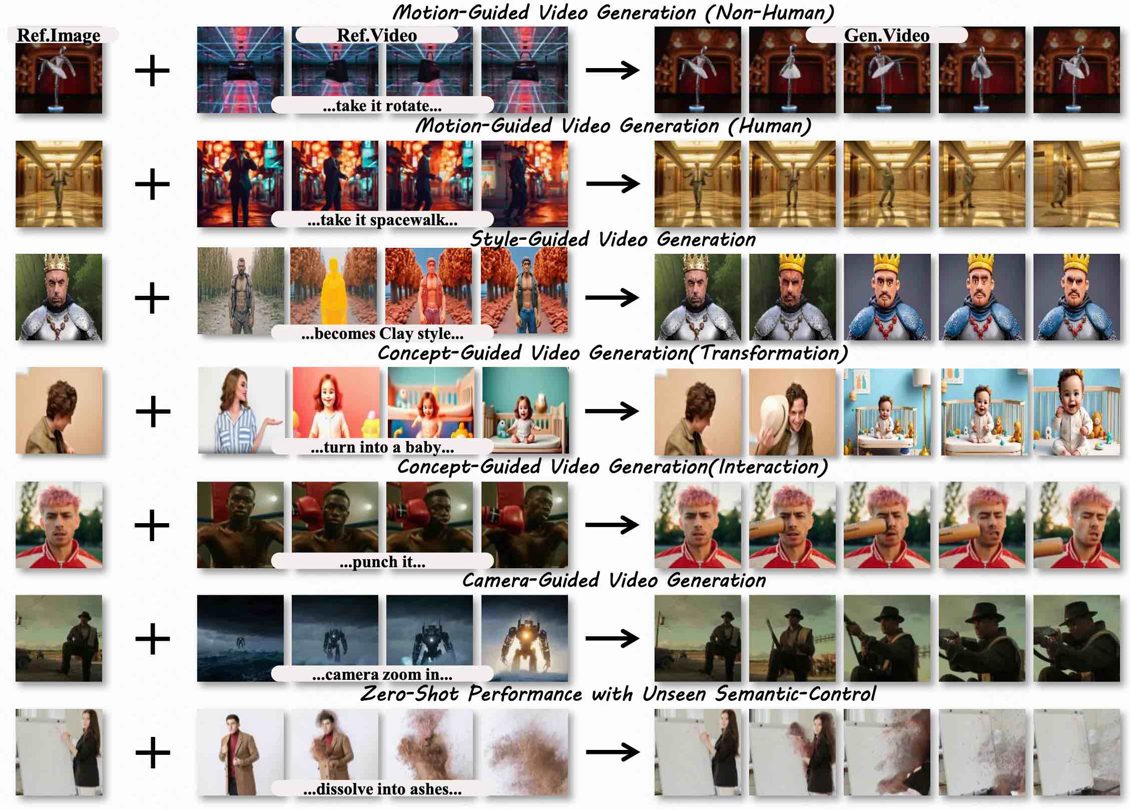
A unified reference-based VFX video generation framework allows users to reproduce diverse dynamic effects from reference videos onto target content.

alt text 

[CVPR 2026 CCF A]  
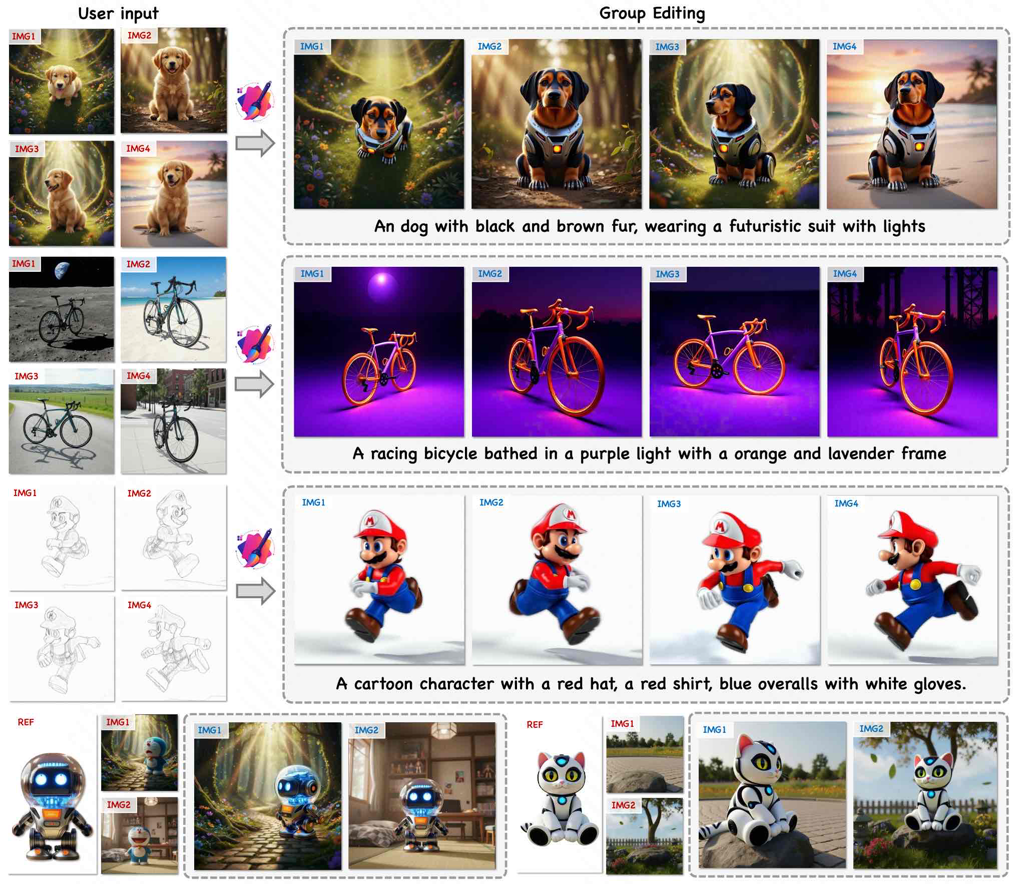
Group Editing: Edit Multiple Images in One Go
Yue Ma, Xinyu Wang, Qianli Ma, Qinghe Wang✉(co-corresponding), Mingzhe Zheng, Xiangpeng Yang, Hao Li, Chongbo Zhao, Jixuan Ying, Harry Yang, Hongyu Liu✉, Qifeng Chen
[Paper] [Project Page] [Code]

A unified group-image editing framework enables users to apply consistent and diverse editing across multiple related images by leveraging explicit geometric correspondences and implicit video priors.

alt text 

[CVPR 2026 Findings CCF A]  
Video2LoRA: Unified Semantic-Controlled Video Generation via Per-Reference-Video LoRA
Zexi Wu, Qinghe Wang✉(co-corresponding), Jing Dai, Baolu Li, Yiming Zhang, Yue Ma✉, Xu Jia, Hongming Xu✉
[Paper] [Code]

A unified framework takes a reference video containing the desired semantics as input and employs a HyperNetwork to generate lightweight, semantic-specific LoRA modules for semantic-controllable video generation.


[SIGGRAPH 2026 CCF A]  
EasyVFX: Frequency-Driven Decoupling for Resource-Efficient VFX Generation
Yue Ma, Xu Ye, Qinghe Wang✉(co-corresponding), Yucheng Wang, Hongyu Liu, Yinhan Zhang, Xinyu Wang, Yuanpeng Che, Shanhui Mo, Paul Liang, Fangneng Zhan✉, Qifeng Chen
[Paper] [Project Page] [Code]

A VFX video generation framework takes a reference VFX video as input and employs a frequency-aware decoupling mechanism to enable resource-efficient, high-fidelity visual effect transfer for controllable video generation.

alt text 

[SIGGRAPH 2025 CCF A]  
CineMaster: A 3D-Aware and Controllable Framework for Cinematic Text-to-Video Generation
Qinghe Wang*, Yawen Luo*(co-first), Xiaoyu Shi✉, Xu Jia✉, Huchuan Lu, Tianfan Xue✉, Xintao Wang, Pengfei Wan, Di Zhang, Kun Gai.
[Paper] [Project Page]

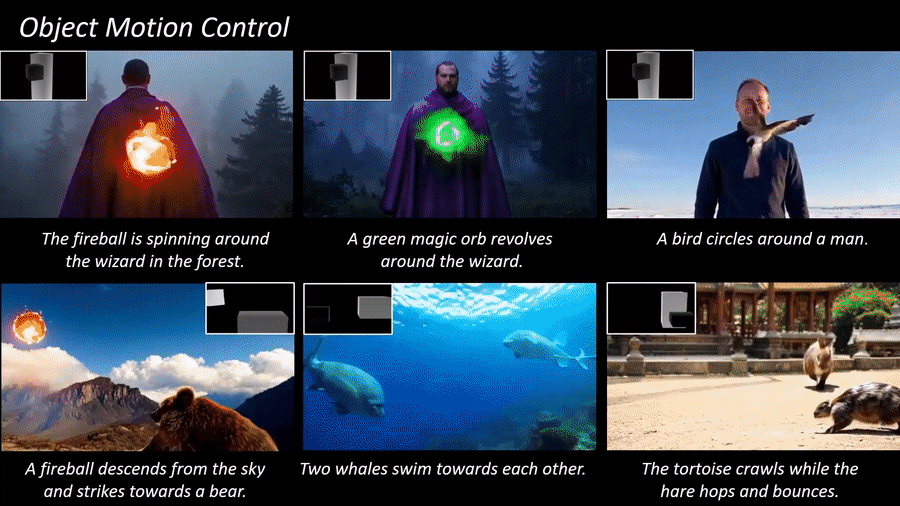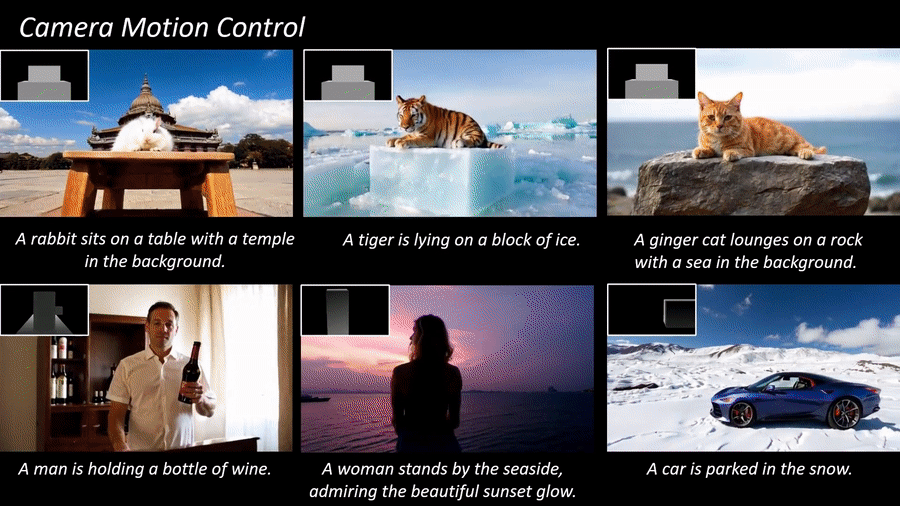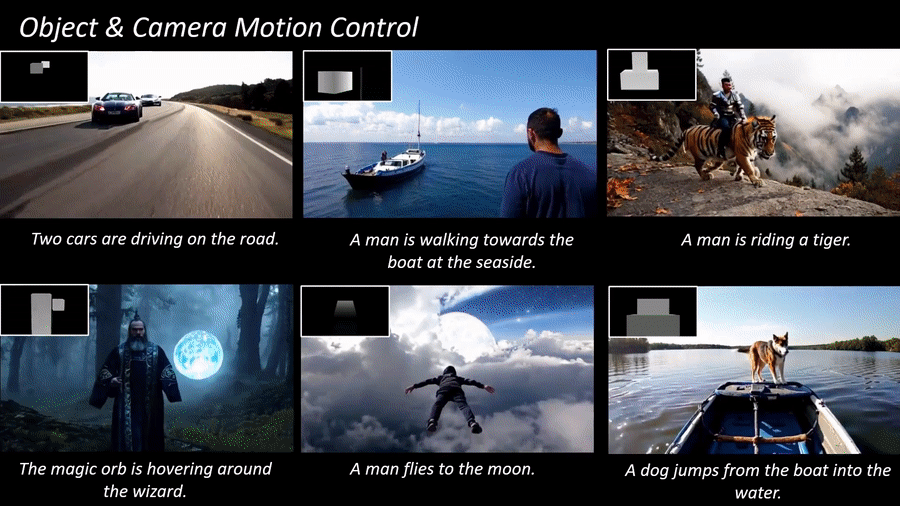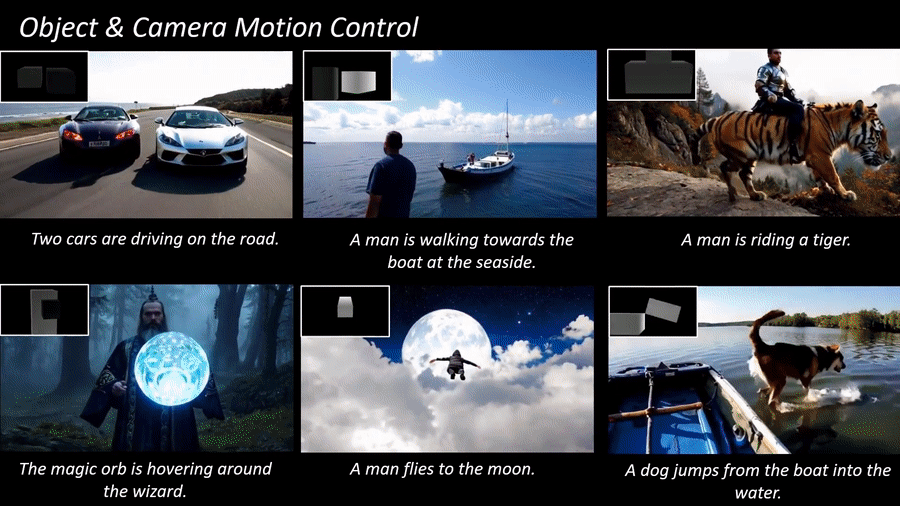
A 3D-aware and controllable text-to-video generation method allows users to manipulate objects and camera jointly in 3D space for high-quality cinematic video creation.

alt text 

[TIP 2025 CCF A; CAS-JCR Q1 Top]  
CharacterFactory: Sampling Consistent Characters with GANs for Diffusion Models
Qinghe Wang, Baolu Li, Xiaomin Li, Bing Cao, Liqian Ma, Huchuan Lu, Xu Jia✉.
[Gradio Demo] [Paper] [Project Page] [Code]

An end-to-end framework allows users to sample new characters with consistent identities for new character creation.

alt text 

[TMM 2025 CCF A; CAS-JCR Q1 Top]  
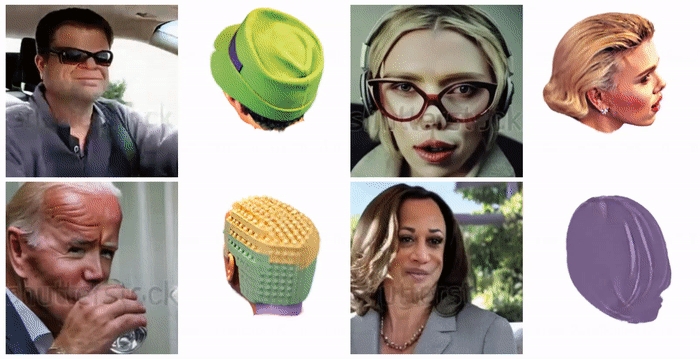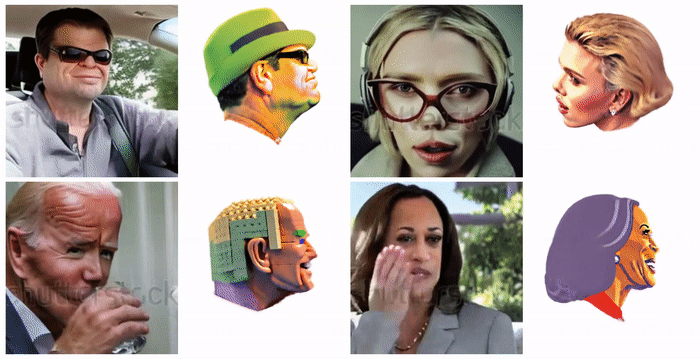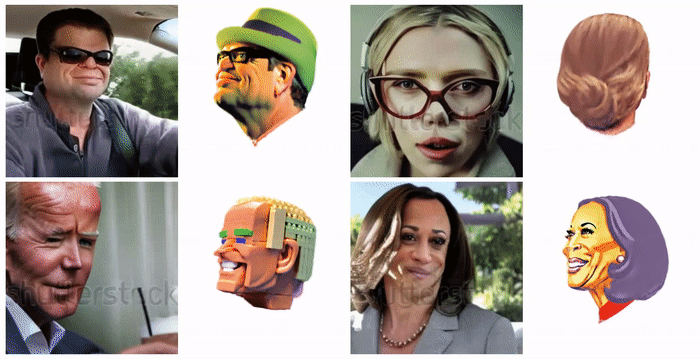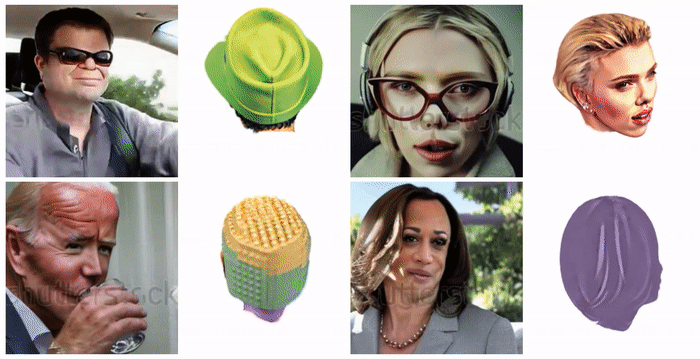
StableIdentity: Inserting Anybody into Anywhere at First Sight
Qinghe Wang, Xu Jia✉, Xiaomin Li, Taiqing Li, Liqian Ma, Yunzhi Zhuge, Huchuan Lu.
[Paper] [Project Page] [Code] [Yann LeCun: OMG]

A framework enables identity-consistent generation with just one face image, and seamless integration with video/3D generation without finetuning.

alt text 

[Arxiv 2023]  
HS-Diffusion: Semantic-Mixing Diffusion for Head Swapping
Qinghe Wang, Lijie Liu, Miao Hua, Pengfei Zhu, Wangmeng Zuo, Qinghua Hu, Huchuan Lu, Bing Cao✉.
[Paper] [Code]

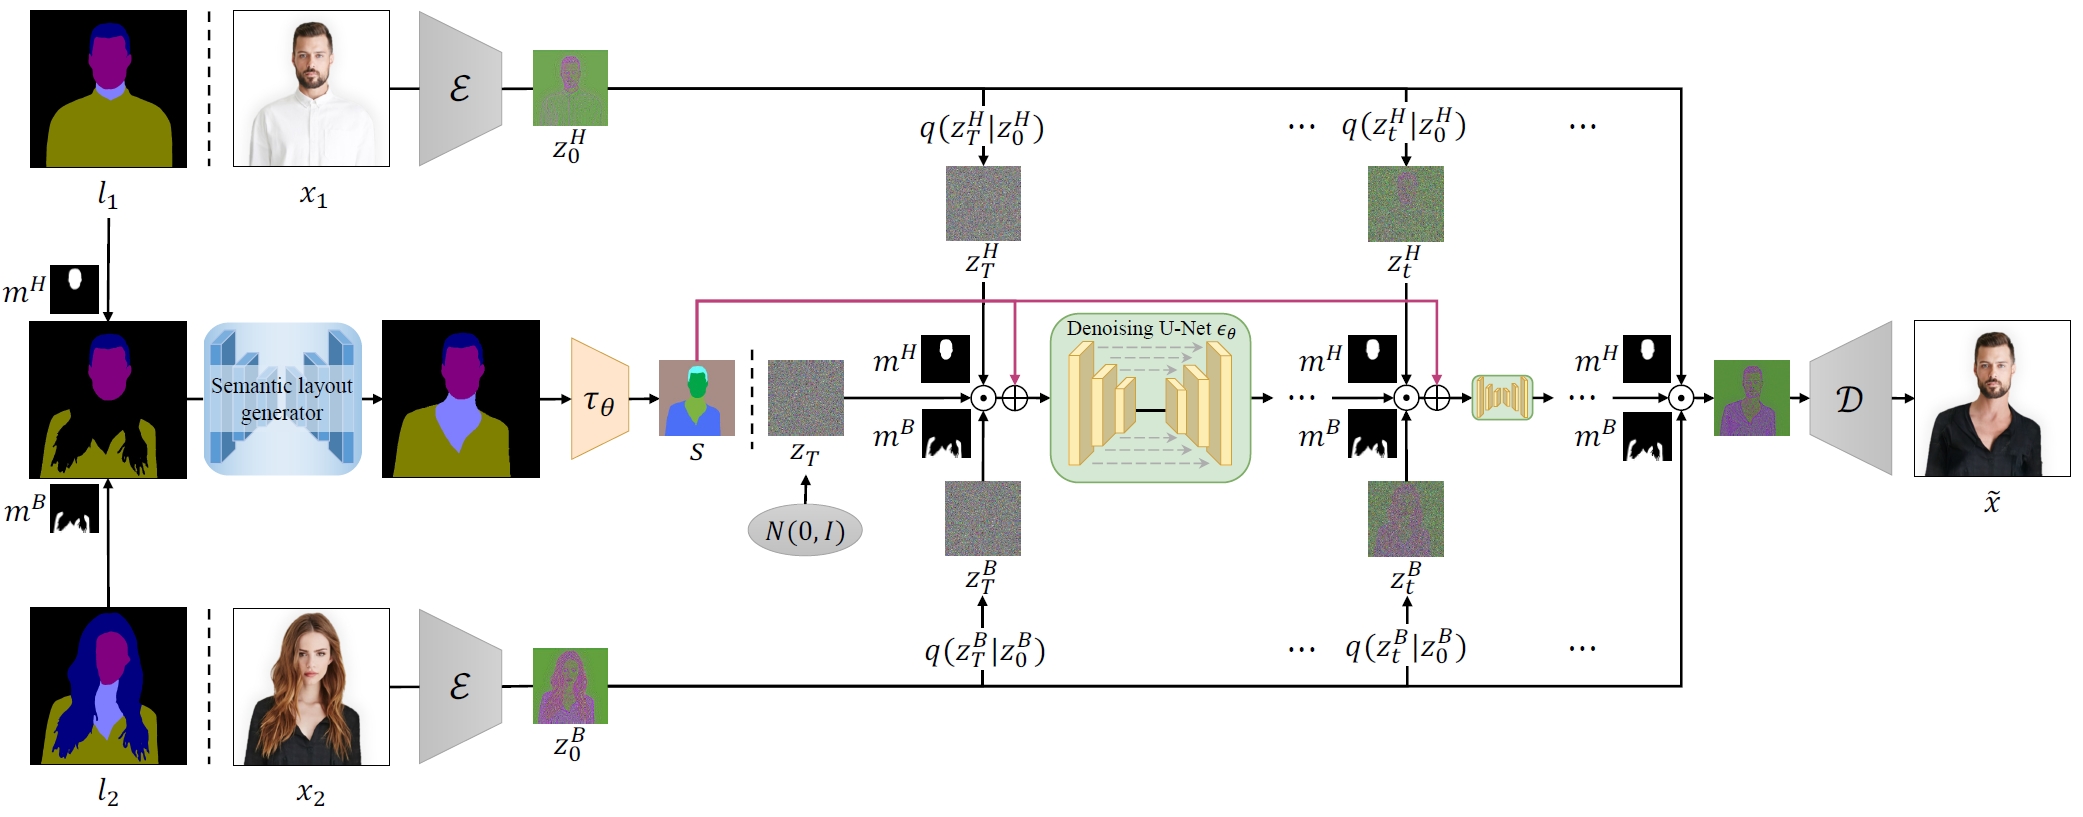
A framework enables seamless head swapping, preserving both head and body details while generating natural transition regions.

alt text 

[TNNLS 2023 CAS-JCR Q1 Top; CCF B]  
Multi-view knowledge ensemble with frequency consistency for cross-domain face translation
Bing Cao, Qinghe Wang, Pengfei Zhu✉, Qinghua Hu, Dongwei Ren, Wangmeng Zuo, Xinbo Gao.
[Paper] [Code]

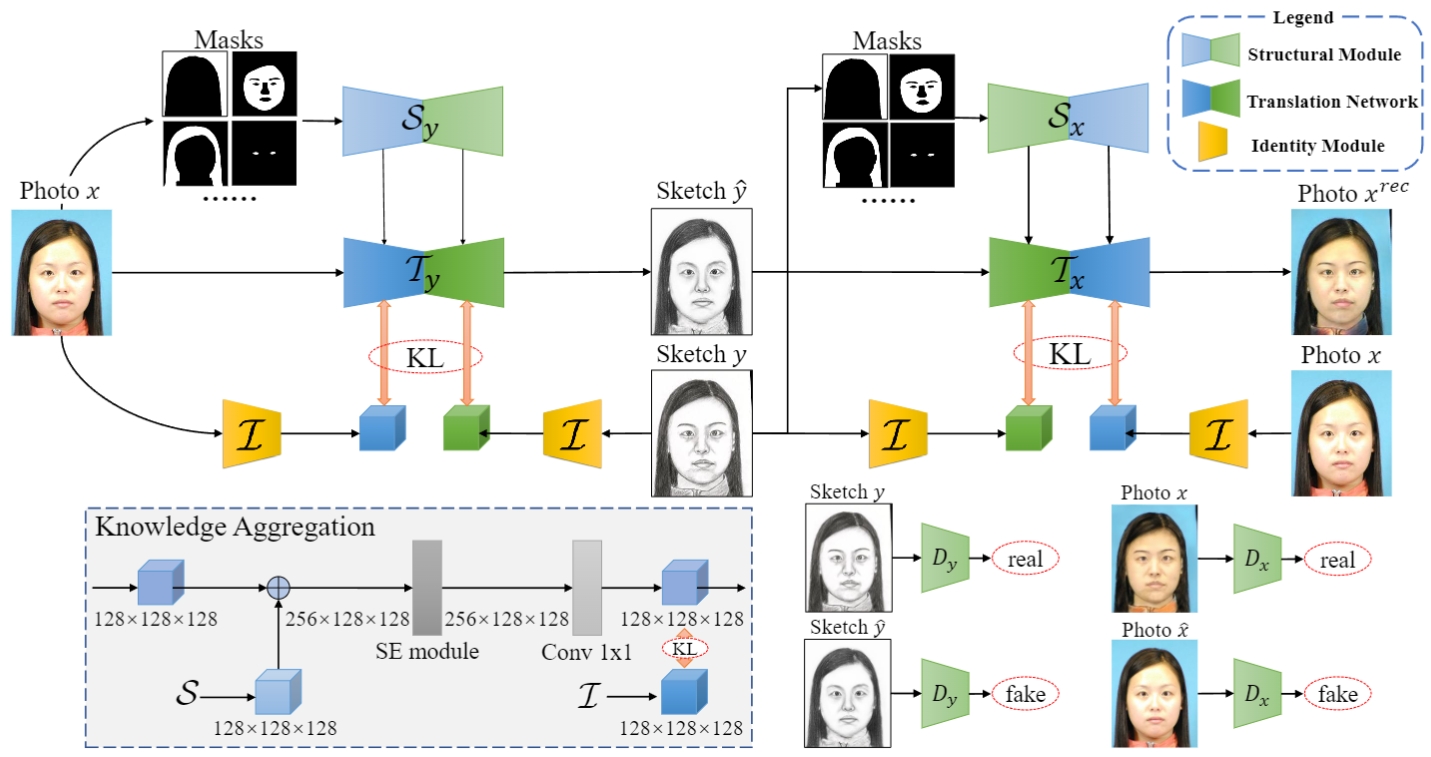
A framework enables cross-domain face translation with structural and identity preservation.

alt text 

[中国科学:信息科学 2022 CCF A类中文期刊]  
基于自判别循环生成对抗网络的人脸图像翻译 (Nickname: CycleGAN--)
王清和, 曹兵✉, 朱鹏飞, 王楠楠, 胡清华, 高新波.
[Paper] [Code]

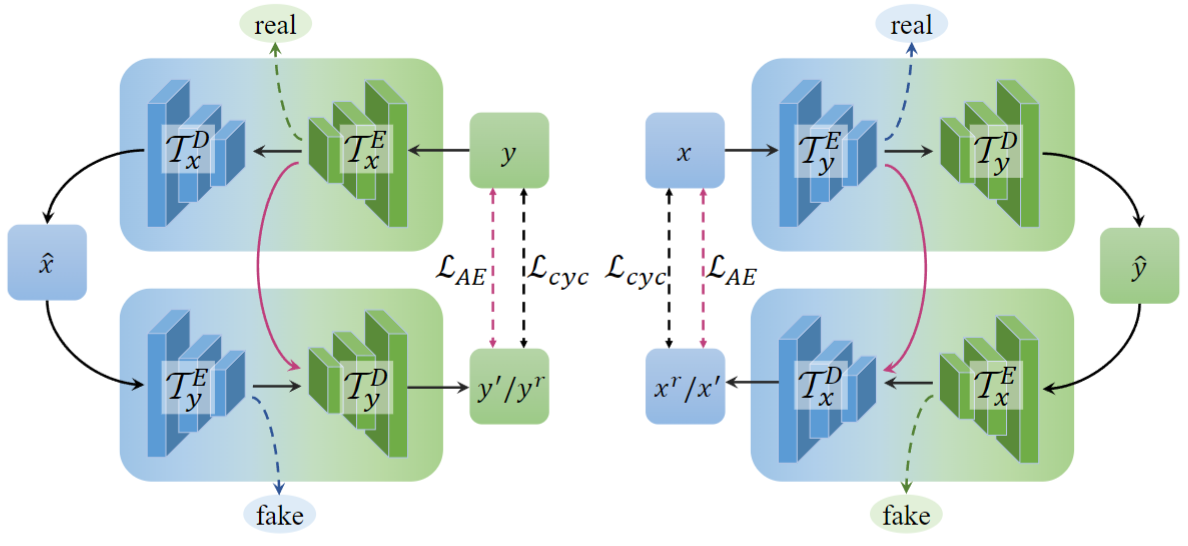
A framework enables cross-domain face translation by integrating two the discriminators into two encoders.

Service

I serve as a reviewer for TPAMI, TIP, SIGGRAPH, CVPR, ECCV, TNNLS, TCSVT, ICLR, ACM MM, ICME, MIR, etc.

Awards